Retrieval-Augmented Generation (RAG): A Complete Guide to Architecture, Workflow, Use Cases, and Implementation
Category: Artificial Intelligence | Generative AI | Software Engineering
1. Introduction
Large Language Models (LLMs) have transformed how applications interact with users by enabling natural language understanding, content generation, summarization, and conversational experiences.
However, traditional LLMs have limitations. They may not know an organization's private information, may lack access to the latest data, and can occasionally generate incorrect information when sufficient context is unavailable.
Retrieval-Augmented Generation (RAG) addresses these limitations by combining information retrieval with the natural language generation capabilities of an LLM.
Instead of relying exclusively on information learned during training, a RAG-based application retrieves relevant information from external knowledge sources and provides that information to the LLM before generating a response.
This enables applications to answer questions using company documents, technical documentation, policies, databases, manuals, reports, and other knowledge repositories.
2. What Is Retrieval-Augmented Generation (RAG)?
Retrieval-Augmented Generation is an AI architecture that enhances the response-generation capabilities of a Large Language Model by retrieving relevant information from an external knowledge source and using that information as contextual input.
RAG combines three fundamental operations:
2.1 Retrieval
The system searches external knowledge sources to identify information relevant to the user's question.
2.2 Augmentation
The retrieved information is added to the prompt as contextual knowledge, helping the LLM understand what information it should use to answer the question.
2.3 Generation
The LLM processes the user query together with the retrieved context and generates a meaningful response in natural language.
The result is an AI application capable of answering questions using knowledge that may not have been part of the model's original training data.
3. Why Do We Need RAG?
Traditional LLMs are powerful, but they are not automatically connected to an organization's internal data or continuously updated information.
Consider an enterprise application containing thousands of documents, including employee handbooks, HR policies, technical documentation, project specifications, customer support knowledge bases, product manuals, financial reports, and internal business procedures.
A traditional LLM cannot automatically access these documents simply because they exist within the organization.
RAG solves this problem by introducing a retrieval mechanism that allows the AI application to search relevant data at runtime.
Limitations of Traditional LLMs
| Limitation | Description |
|---|---|
| Knowledge limitations | The model may not know private organizational information. |
| Knowledge cutoff | Training data may not contain the latest information. |
| Hallucinations | The model may generate plausible but incorrect answers. |
| No direct document access | The model cannot access private documents without integration. |
| Lack of traceability | Answers may not provide references to original sources. |
| Expensive customization | Fine-tuning is not always practical for frequently changing information. |
How RAG Addresses These Problems
| Problem | RAG Solution |
|---|---|
| Private information | Retrieves information from internal knowledge sources. |
| Frequently updated data | Re-indexes updated documents without retraining the LLM. |
| Incorrect answers | Provides relevant context to improve answer grounding. |
| Document search | Enables semantic search across large knowledge repositories. |
| Source verification | Stores metadata that can be used to return source references. |
| Knowledge scalability | External knowledge can grow independently of the LLM. |
Note: RAG can significantly reduce hallucinations, but it does not eliminate them. Retrieval quality, prompt design, data quality, model behavior, and validation all influence the final answer.
4. High-Level RAG Architecture
A RAG system generally consists of two independent but connected pipelines:
- Data Ingestion Pipeline: Processes external knowledge and prepares it for retrieval.
- Query Processing Pipeline: Retrieves relevant knowledge and generates an answer.
The ingestion pipeline prepares data in advance, while the query pipeline executes whenever a user asks a question.
RAG Architecture Diagram
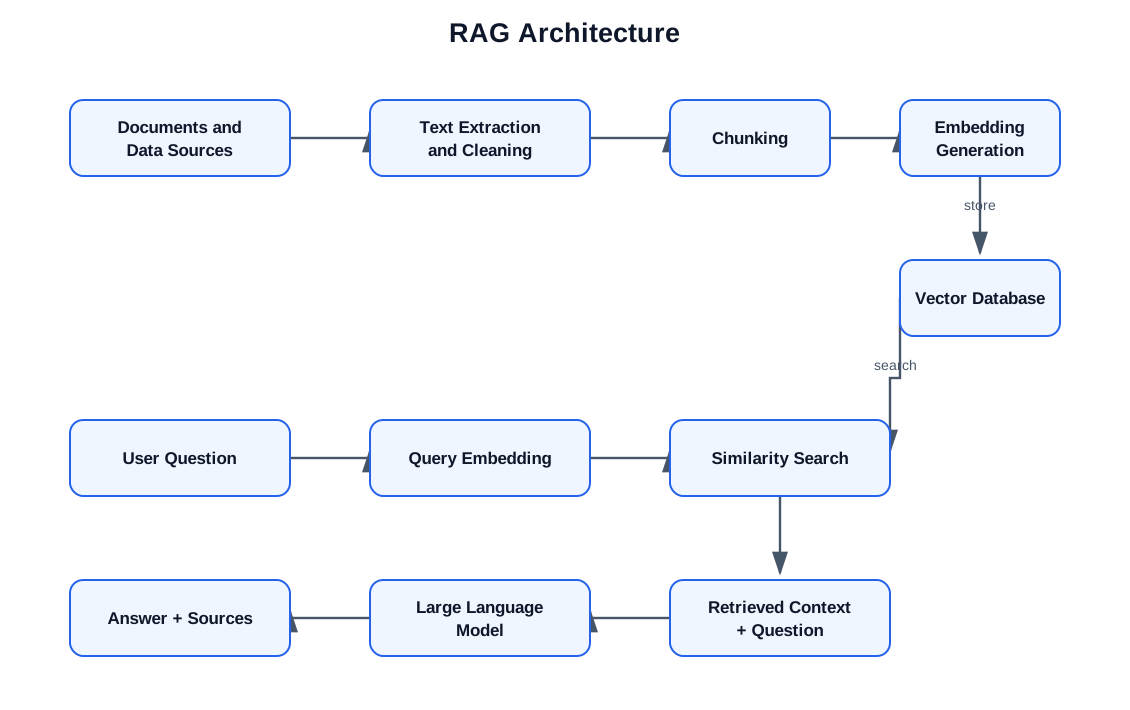
Architecture Components
| Component | Responsibility |
|---|---|
| Data Sources | Provide documents and information. |
| Document Processor | Extracts and cleans text. |
| Chunking Engine | Splits documents into smaller searchable units. |
| Embedding Model | Converts text into numerical vectors. |
| Vector Database | Stores embeddings and associated information. |
| Retriever | Finds relevant chunks for a query. |
| Prompt Builder | Combines question, context, and instructions. |
| LLM | Generates a natural language response. |
| Response Layer | Returns the answer and source references. |
5. Understanding the Data Ingestion Pipeline
The Data Ingestion Pipeline transforms raw documents into a searchable knowledge representation that can be efficiently used by an AI application.
Documents must first be extracted, processed, divided into smaller sections, converted into embeddings, and stored in a vector database.
This pipeline usually runs when documents are uploaded, imported, or updated—not every time a user asks a question.
5.1 Step 1 – Data Collection
Typical data sources include PDF files, Word documents, text files, HTML web pages, database records, API responses, knowledge bases, and application-specific records.
5.2 Step 2 – Text Extraction
Documents may contain text in different formats. The system extracts the text and converts it into a format that can be processed by the application.
Example:
Annual Leave Policy

Employees are eligible for 24 annual leave days per year.

Employees can apply for sick leave
in accordance with company policies.
Technologies that can be used for text extraction include Apache PDFBox and Apache Tika. Scanned PDFs may not contain extractable text and generally require Optical Character Recognition (OCR).
5.3 Step 3 – Text Cleaning and Normalization
Extracted text may contain unnecessary whitespace, repeated headers, broken lines, page artifacts, or irrelevant formatting.
Common operations include removing unnecessary whitespace, normalizing line breaks, removing repeated headers and footers, cleaning unwanted symbols, handling encoding issues, and preserving meaningful document structure.
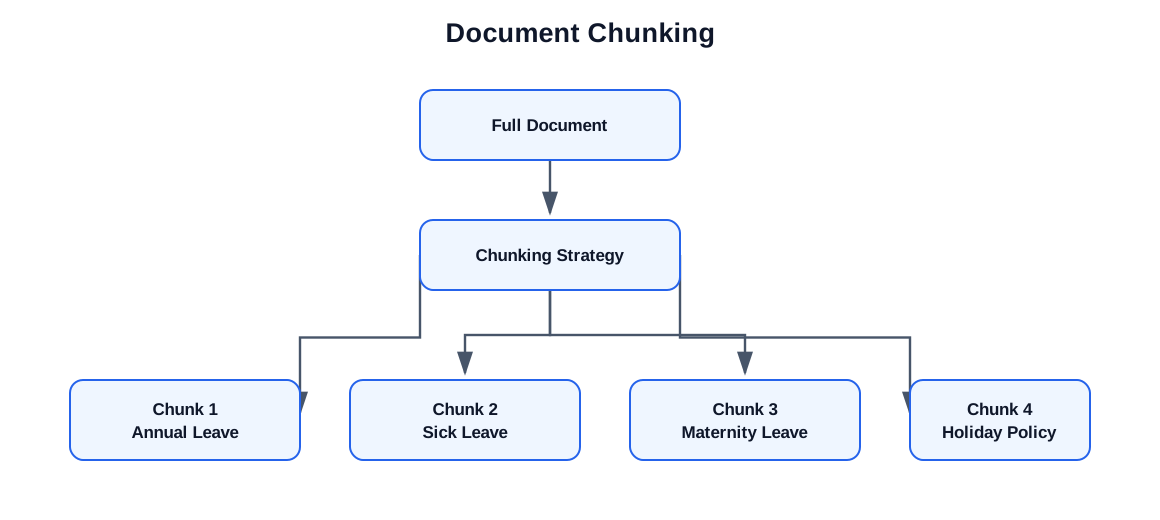
5.4 Step 4 – Chunking
Chunking is the process of dividing large documents into smaller, manageable text segments.
Instead of storing an entire document as a single searchable unit, the system creates smaller pieces called chunks.
Why is chunking important?
- Large documents may contain multiple unrelated topics.
- Relevant information may be buried inside long documents.
- Smaller segments improve retrieval precision.
- LLM context windows have practical limits.
- Smaller relevant context can reduce unnecessary token consumption.
Chunking Diagram
Chunking Strategies
| Strategy | Description | Best suited for |
|---|---|---|
| Fixed-size chunking | Splits text based on token or character limits | Simple documents |
| Recursive chunking | Splits using paragraphs, sentences, and smaller boundaries | General-purpose RAG |
| Semantic chunking | Groups text based on meaning | Context-sensitive content |
| Document-aware chunking | Uses sections, headings, tables, and structure | Policies and technical manuals |
Chunk Size and Overlap
Chunk size determines how much text is stored in a single chunk. Chunk overlap preserves some text from the end of one chunk in the beginning of the next chunk to reduce loss of context.
For a starting experiment, a chunk size of approximately 500 tokens with 50–100 tokens of overlap can be tested.
These are starting values, not universal rules. Chunk size should be optimized based on document structure, retrieval quality, embedding model behavior, and the nature of user questions.
5.5 Step 5 – Embedding Generation
Once documents have been divided into chunks, the system converts each chunk into a numerical vector using an embedding model.
An embedding is a numerical representation of text that captures semantic characteristics of its meaning.
For example, the following sentences are semantically similar:
- How many annual leaves do employees receive?
- What is the yearly vacation allowance?
- How much paid leave can an employee take?
Although the sentences use different words, their meanings are closely related.
An embedding model represents these sentences as vectors in a mathematical space where semantic relationships can be compared.
Example: Text to Vector
Input text:
Employees are eligible for 24 annual leaves per year.Illustrative embedding output:
[0.124, -0.532, 0.891, 0.216, 0.735, -0.149, ...]These values are numerical representations used for similarity comparison.
The embedding model is used during both document indexing and question processing so that the stored chunks and user queries can be compared in a compatible vector space.
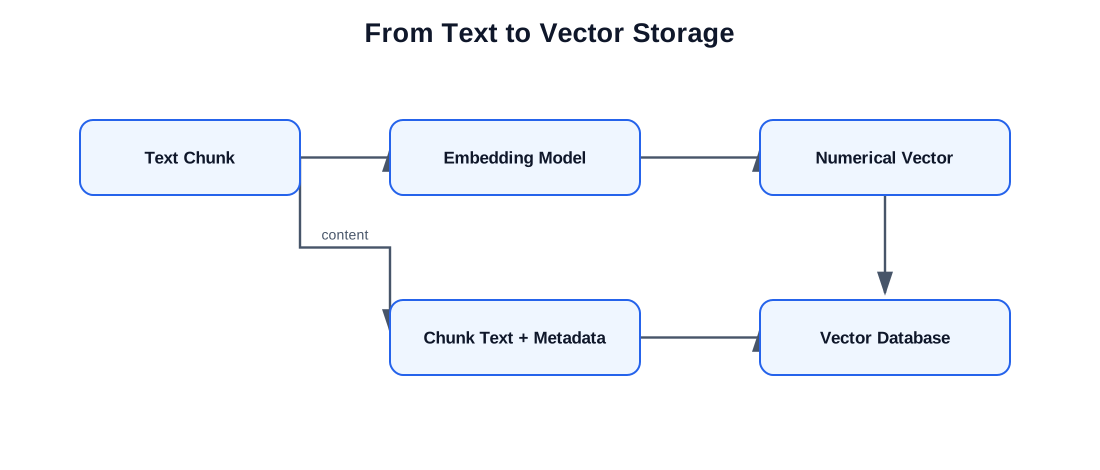
5.6 Step 6 – Store Data in a Vector Database
After generating embeddings, the application stores them in a vector database along with the original chunk content and metadata.
A stored record may contain chunk ID, document ID, text content, embedding vector, page number, document name, tenant ID, category, and created or updated timestamp.
Example:
{
  "chunkId": "chunk-001",
  "documentId": "doc-101",
  "tenantId": "tenant-01",
  "documentName": "LeavePolicy.pdf",
  "pageNumber": 4,
  "content": "Employees are eligible for 24 annual leaves per year.",
  "embedding": [0.124, -0.532, 0.891, 0.216]
}
Common vector database options include PostgreSQL with pgvector, Pinecone, Weaviate, Milvus, and Chroma.
The vector database stores numerical vectors and provides retrieval mechanisms, metadata filtering, indexing strategies, and other capabilities depending on the platform.
6. Understanding the Query Processing Pipeline
Once documents have been processed and indexed, the application is ready to answer questions.
The Query Processing Pipeline executes whenever a user submits a query.
Query Processing Diagram
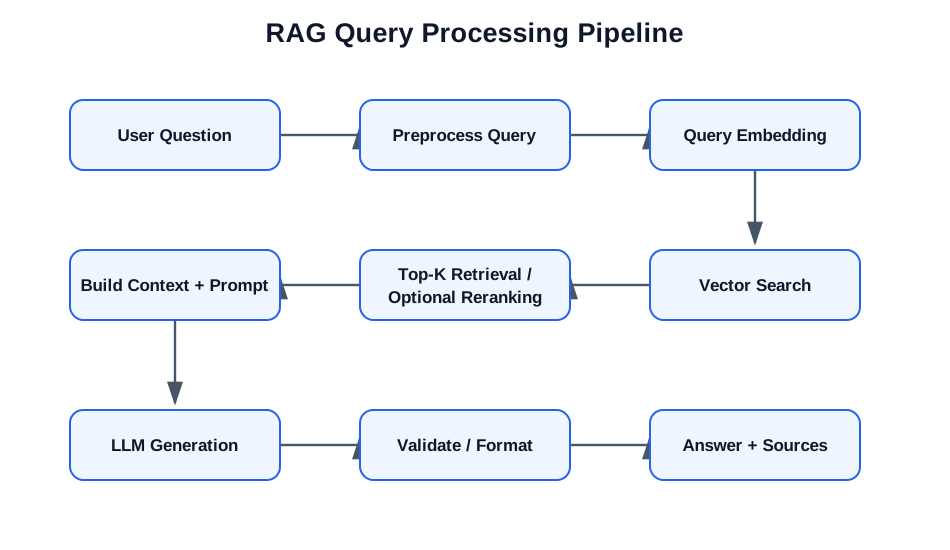
6.1 Step 1 – User Submits a Question
Example: "How many annual leaves are employees entitled to?"
The backend receives the question through an API endpoint.
{
  "question": "How many annual leaves are employees entitled to?"
}
6.2 Step 2 – Generate the Query Embedding
The application sends the user question to the embedding model. The question is converted into a numerical vector.
6.3 Step 3 – Similarity Search
The vector database compares the query embedding with the embeddings stored during document ingestion.
One commonly used similarity metric is Cosine Similarity:
Cosine Similarity(A,B) = (A · B) / (||A|| × ||B||)
Cosine similarity measures the similarity between the directions of two vectors.
For normalized vectors, a higher similarity score generally indicates that the vectors are more closely aligned.
Depending on the vector database and configuration, retrieval may use cosine similarity, inner product, Euclidean distance, or other vector search metrics.
6.4 Step 4 – Retrieve Top K Chunks
The retriever returns the most relevant chunks based on search results.
| Retrieved Chunk | Similarity |
|---|---|
| Annual leaves are 24 days | 0.94 |
| Sick leaves are 12 days | 0.76 |
| Maternity leave is 26 weeks | 0.63 |
These scores are illustrative.
The Top K parameter determines how many chunks should be retrieved. Retrieving too few chunks may omit important information. Retrieving too many may introduce irrelevant context and increase token consumption.
6.5 Step 5 – Context Construction
The retrieved chunks are combined into a context section.
Context:

Source: LeavePolicy.pdf
Page: 4

Employees are eligible for 24 annual leave
days per year.

Source: LeavePolicy.pdf
Page: 5

Employees must submit leave requests
through the HR portal.
6.6 Step 6 – Prompt Construction
The prompt combines system instructions, retrieved context, and the user's question.
SYSTEM INSTRUCTION:

You are an enterprise knowledge assistant.

Answer questions using the provided context.

Do not invent facts.

If the context does not contain the answer,
state that the information is unavailable.

CONTEXT:

Employees are eligible for 24 annual leave
days per year.

QUESTION:

How many annual leaves do employees receive?
6.7 Step 7 – LLM Response Generation
The LLM interprets the question, analyzes the context, and generates a natural language response.
Example:
"Employees are entitled to 24 annual leave days per year, according to the Leave Policy."
6.8 Step 8 – Return the Answer with Sources
A production RAG application should ideally return both the generated answer and the sources used to support it.
{
  "answer": "Employees are entitled to 24 annual leave days per year.",
  "sources": [
    {
      "documentName": "LeavePolicy.pdf",
      "pageNumber": 4,
      "section": "Annual Leave"
    }
  ]
}
Source references improve transparency and allow users to verify information against the original document.
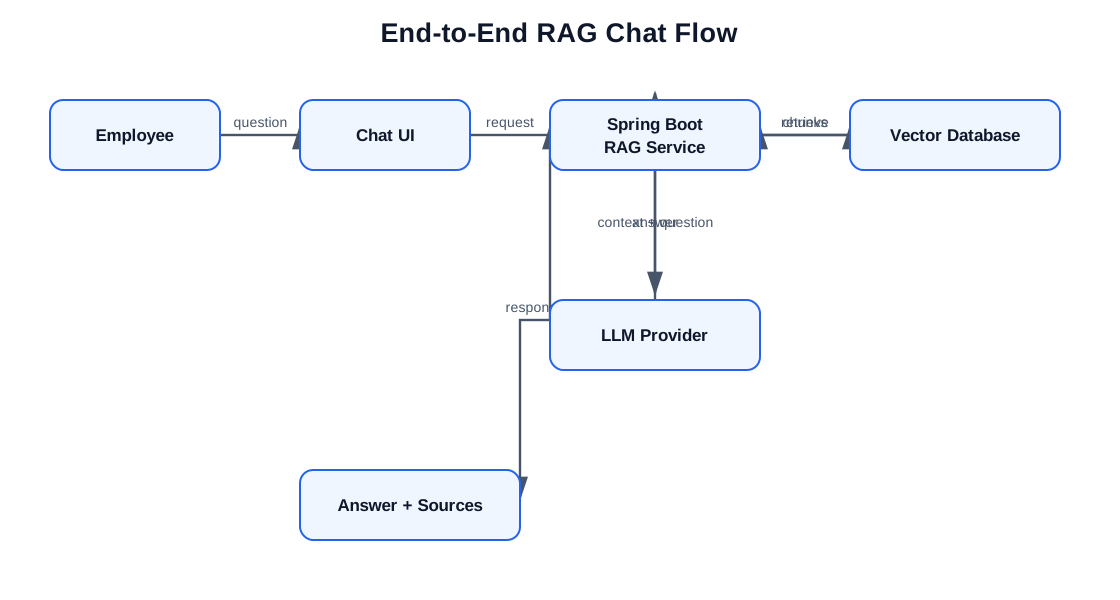
7. RAG Workflow: Complete End-to-End Example
Consider an enterprise HR Knowledge Assistant.
A company wants employees to access HR information without manually searching hundreds of policy documents.
- Upload Documents: The administrator uploads Employee Handbook.pdf, Leave Policy.pdf, Payroll Policy.pdf, and Work From Home Policy.pdf.
- Process Documents: The backend extracts text, removes unnecessary formatting, and splits documents into chunks.
- Generate Embeddings: The embedding model generates vector representations for each chunk.
- Store the Chunks: The chunks, embeddings, and metadata are stored in PostgreSQL with pgvector.
- Employee Asks a Question: "Can I work from home three days a week?"
- Retrieve Relevant Information: The system searches the vector database and retrieves relevant chunks from the Work From Home Policy.
- Generate Answer: The retrieved context is provided to the LLM.
- Return Answer: The application returns the answer and relevant document source.
8. Vector Database and Embeddings: How They Work Together
An embedding model creates numerical representations of text, while the vector database stores those representations and enables efficient similarity retrieval.
8.1 Keyword Search
Keyword search focuses on matching exact words, terms, phrases, or lexical patterns.
Example:
Query: "Annual leave"
Search result: "Annual leave policy"
This is useful when users know the exact terms or are searching for identifiers, codes, names, or specific phrases.
8.2 Semantic Search
Semantic search focuses on the meaning of the query rather than requiring exact word matches.
Example:
Query: "How much vacation can I take?"
Document: "Employees are eligible for 24 annual leave days."
Even though the query and document use different wording, semantic search may retrieve the relevant content.
8.3 Hybrid Search
Hybrid search combines keyword search and semantic search.
This is particularly useful for enterprise knowledge systems because users may search using natural language while also including exact identifiers, technical terms, employee codes, policy names, or product numbers.
9. RAG vs. Fine-Tuning vs. Prompt Engineering
These approaches solve different problems and should not be considered interchangeable.
| Feature | Prompt Engineering | RAG | Fine-Tuning |
|---|---|---|---|
| Primary purpose | Instruction control | Knowledge retrieval | Behavior adaptation |
| External knowledge at runtime | Not inherently | Yes | Not inherently |
| Updating knowledge | Change prompt | Update index/data | Usually retraining |
| Private documents | Manually provide context | Retrieve dynamically | May be incorporated into training |
| Source citations | Not automatic | Can be implemented | Not automatic |
| Best use | Output behavior | Dynamic knowledge | Specialized behavior |
Which Approach Should You Choose?
- Use Prompt Engineering to control instructions, tone, output format, and behavior.
- Use RAG when the application needs access to external, private, or frequently updated information.
- Use Fine-Tuning when the model needs to adapt to specialized tasks, patterns, or behavior that prompting alone may not achieve.
Many production systems combine Prompt Engineering and RAG. Fine-tuning may be added when a specific need justifies it.
10. Real-World Applications of RAG
10.1 Enterprise Knowledge Assistants
Employees can ask questions about internal policies, procedures, company guidelines, benefits, and organizational knowledge without manually searching documents.
10.2 Software Development Assistants
Developers can query codebase documentation, API specifications, architecture documents, troubleshooting guides, and technical knowledge.
10.3 Customer Support Automation
AI can retrieve product information, troubleshooting procedures, FAQs, and customer support documentation to provide relevant answers.
10.4 Financial Document Analysis
Retrieve relevant financial reports, invoices, statements, business records, and financial policies for analysis and question answering.
10.5 Legal Document Intelligence
Search contracts, agreements, clauses, compliance requirements, and legal knowledge repositories.
10.6 Education and Learning Assistants
Students can ask questions based on textbooks, course materials, study notes, and educational resources.
10.7 Research and Healthcare Knowledge
Retrieve research papers, medical literature, clinical reference materials, and scientific knowledge for qualified professionals to review.
11. Benefits of RAG
- Access to Private Knowledge: Connect AI with internal data without incorporating every fact into model training.
- Easy Knowledge Updates: Refresh documents and indexes without retraining the entire model.
- Improved Relevance: Retrieve information relevant to the specific user query.
- Source Transparency: Provide references to supporting documents and pages.
- Flexible Cost Management: Retrieve relevant context instead of supplying entire repositories.
- Scalable Architecture: Separate knowledge storage from the LLM and application logic.
12. Limitations and Challenges of RAG
| Challenge | Description | Possible Solution |
|---|---|---|
| Poor retrieval | Relevant chunks are not found | Improve chunking, embeddings, hybrid search |
| Hallucinations | LLM generates unsupported claims | Grounding instructions and validation |
| Chunking quality | Context is split incorrectly | Semantic or document-aware chunking |
| Latency | Multiple retrieval and AI calls | Caching and optimized search |
| Token cost | Large context sent to LLM | Context compression and reranking |
| Data security | Unauthorized knowledge is retrieved | Access control and metadata filtering |
| Outdated documents | Old information is retrieved | Versioning, re-indexing, deletion |
| Evaluation difficulty | Answers appear correct but lack grounding | Retrieval and answer quality evaluation |
A production implementation should focus on data quality, retrieval accuracy, prompt design, response grounding, security, evaluation, and monitoring.
13. Advanced RAG Techniques
13.1 Hybrid Search
Combines semantic vector search and keyword-based search. Useful for exact product names, technical identifiers, policy numbers, error codes, and natural language questions.
13.2 Reranking
Retrieval may return several relevant chunks, but they may not be in the optimal order. A reranking model evaluates the retrieved results against the query and reorders them according to relevance.
13.3 Metadata Filtering
Metadata filtering restricts retrieval to documents that match specific conditions.
{
  "tenantId": "tenant-101",
  "department": "HR",
  "documentType": "POLICY",
  "status": "ACTIVE"
}
This is particularly important in enterprise and multi-tenant applications.
13.4 Query Rewriting
Users do not always ask precise questions.
Original question: "What about leave?"
Rewritten query: "What is the annual leave entitlement for employees?"
Query rewriting can improve retrieval by making ambiguous questions more explicit.
13.5 Context Compression
Context compression removes redundant or less relevant information while preserving essential facts. This helps reduce token usage, cost, and unnecessary noise in the final answer.
13.6 Agentic RAG
Agentic RAG introduces an AI-driven decision-making layer that can determine whether it needs to search, which tools to use, whether to perform another retrieval, or whether the available evidence is sufficient.
Agentic RAG can be useful for complex research, multi-step analysis, and applications involving multiple knowledge sources or tools. It also increases complexity, latency, and the need for robust controls.
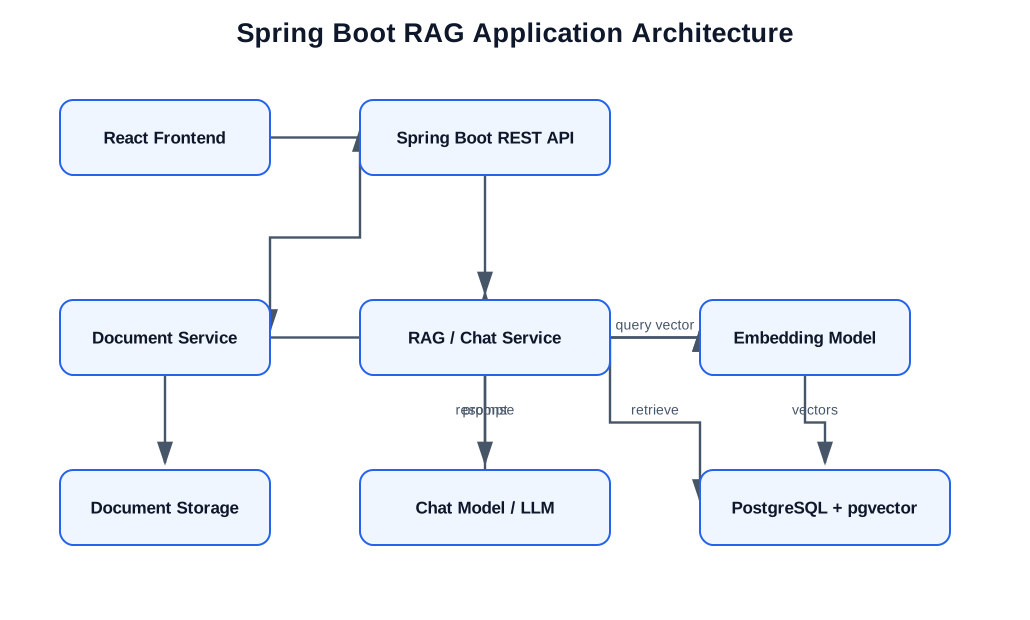
14. Implementing RAG Using Java and Spring Boot
For developers working in the Java ecosystem, RAG can be implemented using Spring Boot and Spring AI.
14.1 Recommended Technology Stack
| Layer | Technology | Responsibility |
|---|---|---|
| Frontend | React.js | Chat interface |
| Backend | Java + Spring Boot | APIs and business logic |
| AI Integration | Spring AI | LLM and RAG integration |
| LLM | GPT or another compatible model | Answer generation |
| Embedding Model | OpenAI or another embedding model | Vector generation |
| Vector Database | PostgreSQL + pgvector | Vector storage and search |
| PDF Processing | Apache PDFBox / Tika | Text extraction |
| Database | PostgreSQL | Metadata and application data |
14.2 Application Architecture
14.3 Suggested Backend Package Structure
com.example.rag
|
+-- api
|   +-- DocumentController.java
|
+-- chat
|   +-- ChatController.java
|   +-- ChatService.java
|   +-- RagService.java
|
+-- document
|   +-- DocumentService.java
|   +-- DocumentProcessor.java
|   +-- DocumentChunker.java
|
+-- embedding
|   +-- EmbeddingService.java
|
+-- repository
|   +-- VectorRepository.java
|
+-- entity
|   +-- DocumentEntity.java
|   +-- DocumentChunkEntity.java
|
+-- dto
|   +-- ChatRequest.java
|   +-- ChatResponse.java
|
+-- config
    +-- AIConfig.java
14.4 Document Upload Flow
The document upload process extracts text, creates chunks, generates embeddings, and persists searchable records.
14.5 Chat Flow
When a user submits a question, the backend generates a query embedding, retrieves relevant chunks, constructs the prompt, calls the LLM, and returns the answer with source references.
14.6 Database Design
PostgreSQL with pgvector can store document metadata, chunk content, and embeddings.
CREATE EXTENSION IF NOT EXISTS vector;

CREATE TABLE documents (
    id UUID PRIMARY KEY,
    file_name VARCHAR(255),
    file_type VARCHAR(50),
    status VARCHAR(50),
    uploaded_at TIMESTAMP
);

CREATE TABLE document_chunks (
    id UUID PRIMARY KEY,
    document_id UUID REFERENCES documents(id),
    content TEXT,
    embedding VECTOR(1536),
    page_number INTEGER
);
The vector dimension must match the output dimensions of the selected embedding model. The dimension of 1536 above is illustrative.
14.7 Suggested API Endpoints
| Method | Endpoint | Purpose |
|---|---|---|
| POST | /api/v1/documents/upload | Upload documents |
| GET | /api/v1/documents | List documents |
| GET | /api/v1/documents/{id} | Retrieve document details |
| DELETE | /api/v1/documents/{id} | Delete a document and its chunks |
| POST | /api/v1/chat/ask | Ask questions using RAG |
| GET | /api/v1/chat/history | Retrieve chat history |
14.8 Spring AI Integration Example
A basic LLM call:
@Service
public class RagService {

    private final ChatClient chatClient;

    public RagService(ChatClient.Builder builder) {
        this.chatClient = builder.build();
    }

    public String askQuestion(String question) {

        return chatClient.prompt()
                .user(question)
                .call()
                .content();
    }
}
The above code is a normal LLM call, not a complete RAG implementation.
RAG requires vector retrieval and the addition of retrieved context to the model prompt.
A conceptual Spring AI implementation using a vector store advisor:
String answer = chatClient.prompt()
        .user(question)
        .advisors(
            QuestionAnswerAdvisor.builder(vectorStore)
                .build()
        )
        .call()
        .content();
This is an illustrative example. Imports, dependencies, and advisor configuration may vary by Spring AI version. Production implementations should also configure metadata filtering, tenant isolation, and source citations.
15. RAG Security and Multi-Tenant Architecture
Security is one of the most important considerations in enterprise RAG systems.
In a multi-tenant application, multiple organizations may share the same backend infrastructure and vector database.
For example:
- Tenant A uploads its HR documents.
- Tenant B uploads its own HR documents.
- Tenant A must never retrieve Tenant B's documents.
- Tenant B must never retrieve Tenant A's documents.
Tenant Isolation Architecture
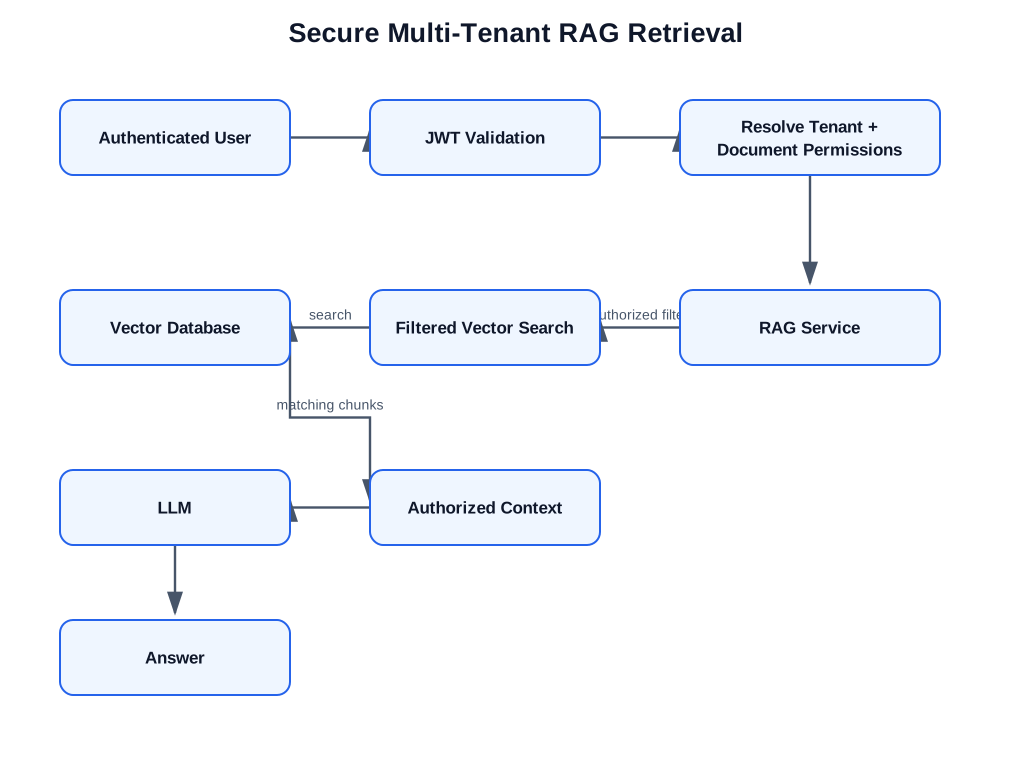
Essential Security Practices
- Derive tenant identity from authenticated server-side context.
- Enforce tenant filters during retrieval.
- Do not trust a tenant ID supplied directly by the client.
- Apply document-level permissions where required.
- Secure document storage and API access.
- Avoid exposing internal data through prompts or logs.
- Validate retrieved content and treat documents as untrusted input.
- Prevent retrieved documents from overriding system instructions.
- Consider database-level isolation or Row Level Security.
Never rely on the LLM to enforce access control. Authorization must be enforced by the backend and database retrieval layer before context reaches the model.
16. RAG Implementation Roadmap
Building a production-ready RAG application requires more than connecting an LLM to a vector database.
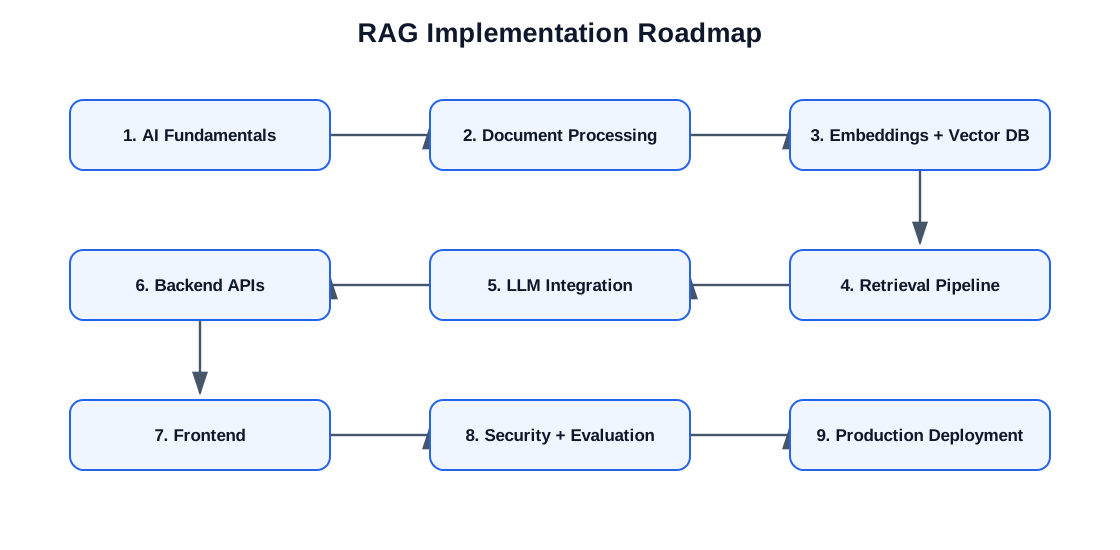
Phase 1 – Understand AI Fundamentals
- Large Language Models
- Tokens and context windows
- Prompt engineering
- Embeddings
- Semantic similarity
- Vector search
Phase 2 – Document Processing
- PDF and DOCX uploads
- Text extraction
- Text cleaning
- Chunking
- Metadata generation
Phase 3 – Embeddings and Vector Storage
- Integrate an embedding model.
- Generate embeddings for chunks.
- Store embeddings in PostgreSQL + pgvector.
- Implement vector indexing.
- Verify stored records.
Phase 4 – Retrieval Pipeline
- Query embedding generation
- Similarity search
- Top K retrieval
- Metadata filtering
- Retrieval evaluation
Phase 5 – LLM Integration
- Prompt construction
- Context injection
- Response generation
- Hallucination reduction
- Response formatting
Phase 6 – Backend API Development
- Document upload APIs
- Document management
- Chat APIs
- Chat history
- Source references
- Exception handling
Phase 7 – Frontend Integration
- Document upload dashboard
- Document list
- Chat interface
- Chat history
- Source citations
- Loading and error states
Phase 8 – Security and Evaluation
- Authentication and authorization
- Tenant isolation
- Document access control
- Retrieval evaluation
- Prompt injection protection
- Logging and monitoring
Phase 9 – Production Deployment
- Containerization
- Environment configuration
- Secrets management
- Background ingestion jobs
- Performance optimization
- CI/CD
- Monitoring
17. How to Evaluate a RAG Application
A RAG application should be evaluated at two separate levels: retrieval quality and response quality.
Retrieval Evaluation
| Metric | What it measures |
|---|---|
| Precision@K | How many retrieved results are relevant |
| Recall@K | How many relevant results were retrieved |
| MRR | How highly the first relevant result is ranked |
| Hit Rate | Whether a relevant result appears among retrieved results |
Generation Evaluation
| Metric | What it measures |
|---|---|
| Faithfulness | Whether the answer is supported by retrieved context |
| Answer Relevance | Whether the response answers the user's question |
| Correctness | Whether the response is factually accurate |
| Context Relevance | Whether the retrieved context is useful |
| Citation Accuracy | Whether cited sources actually support the answer |
A production evaluation process should include representative questions, expected answers, supporting documents, and regular regression testing.
18. RAG vs. Traditional Search
Traditional search and RAG are related, but their primary purpose is different.
| Traditional Search | RAG |
|---|---|
| Returns documents or search results | Returns a generated answer |
| User reads and interprets results | AI synthesizes retrieved information |
| Usually keyword or search ranking based | Can use semantic, keyword, or hybrid retrieval |
| Search relevance is the focus | Retrieval and generation quality are both important |
RAG does not replace traditional search. Many applications benefit from using both: an AI-generated answer with an option to browse original search results.
19. The Future of RAG
RAG is evolving beyond simple document retrieval and answer generation.
- Multimodal RAG: Retrieval across text, images, tables, audio, and video.
- Graph RAG: Using knowledge graphs and relationships between entities to improve retrieval and reasoning.
- Agentic RAG: AI-driven orchestration of retrieval, tools, and multi-step tasks.
- Adaptive Retrieval: Dynamically determining when retrieval is necessary and how much information to retrieve.
- Personalized RAG: Retrieving information based on authorized user preferences and context.
- Real-Time RAG: Using continuously updated data sources.
- Enterprise RAG: Combining access controls, multi-tenancy, auditability, and governed knowledge systems.
As AI applications evolve, RAG will increasingly become part of broader AI application architectures involving knowledge retrieval, tools, workflows, and intelligent agents.
20. Conclusion
Retrieval-Augmented Generation is an architectural approach that connects Large Language Models with external knowledge sources to improve the relevance, accuracy, and contextual usefulness of AI-generated responses.
The fundamental idea behind RAG is simple:
Retrieve the right information first. Give that information to the AI. Generate the answer based on the available context.
Building a reliable RAG application requires careful consideration of document processing, chunking, embedding models, vector databases, retrieval strategies, prompt engineering, security, and evaluation.
The real value of RAG is not simply making an AI chatbot. It is enabling AI systems to interact with an organization's knowledge in a meaningful, contextual, and controlled way.
For developers, RAG opens the door to building intelligent applications that transform static documents, databases, and knowledge repositories into interactive AI-powered experiences.